Applied intelligence for AI builders and operators.
Research and practical guidance from the intersection of enterprise AI, infrastructure, operations, and governance.
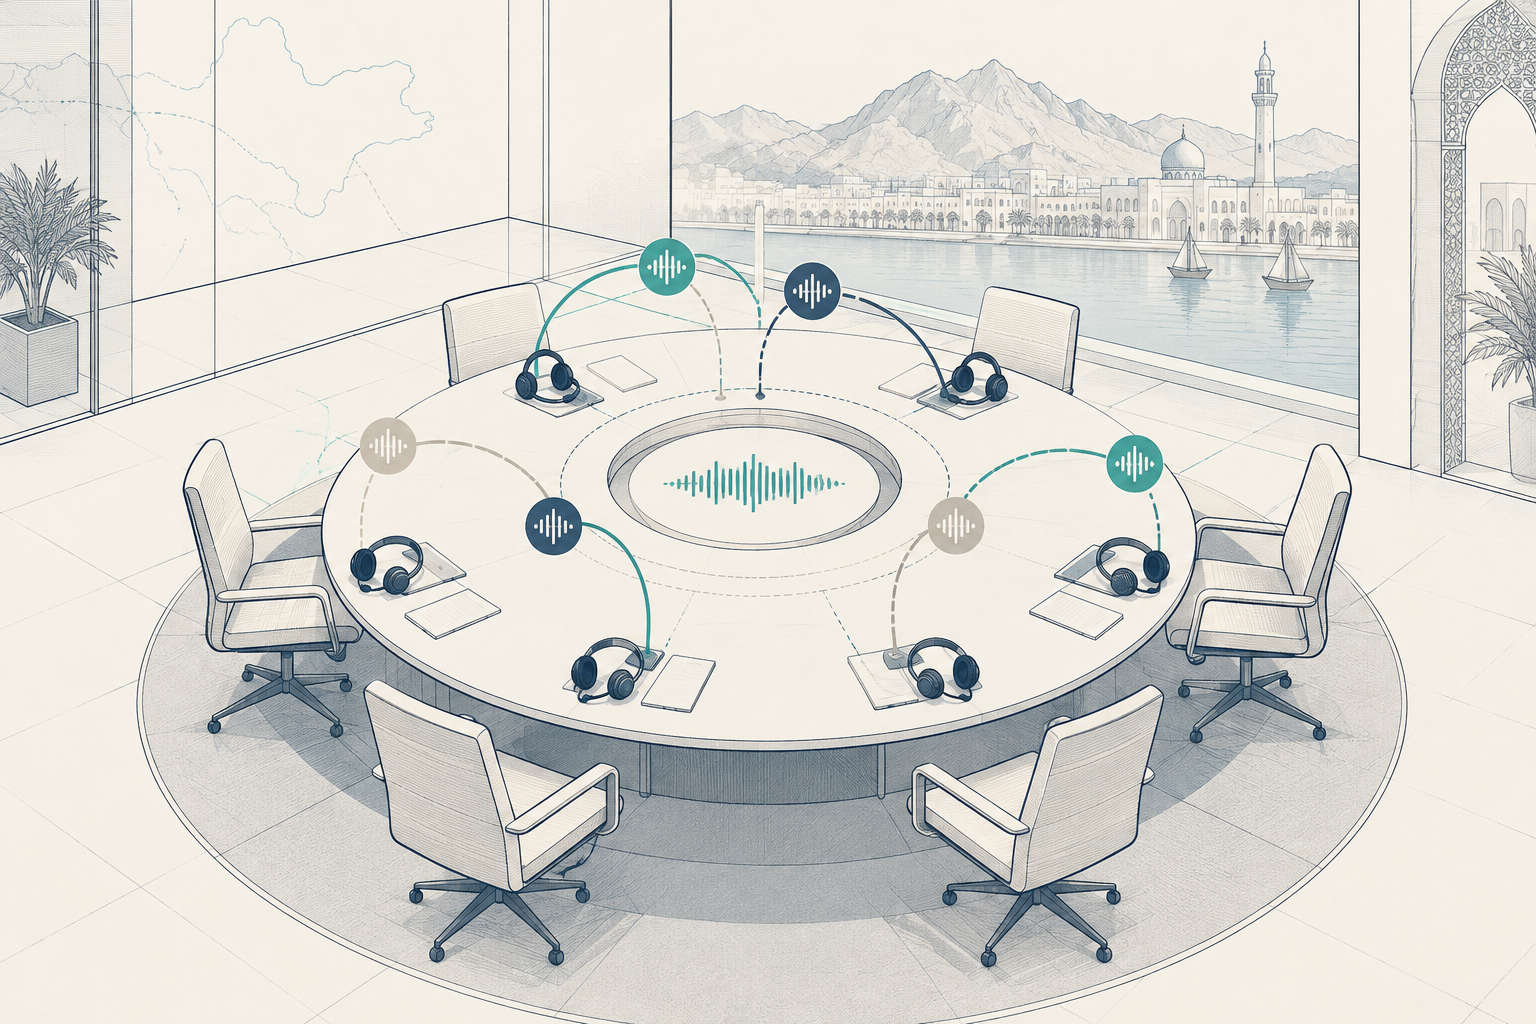
Test Realtime Translation Against the Meeting, Not the Demo
ElevenLabs’ realtime translation alpha puts the focus on meeting acceptance tests: turn-taking, interruptions, terminology, comprehension and delay across verified language pairs.
10 min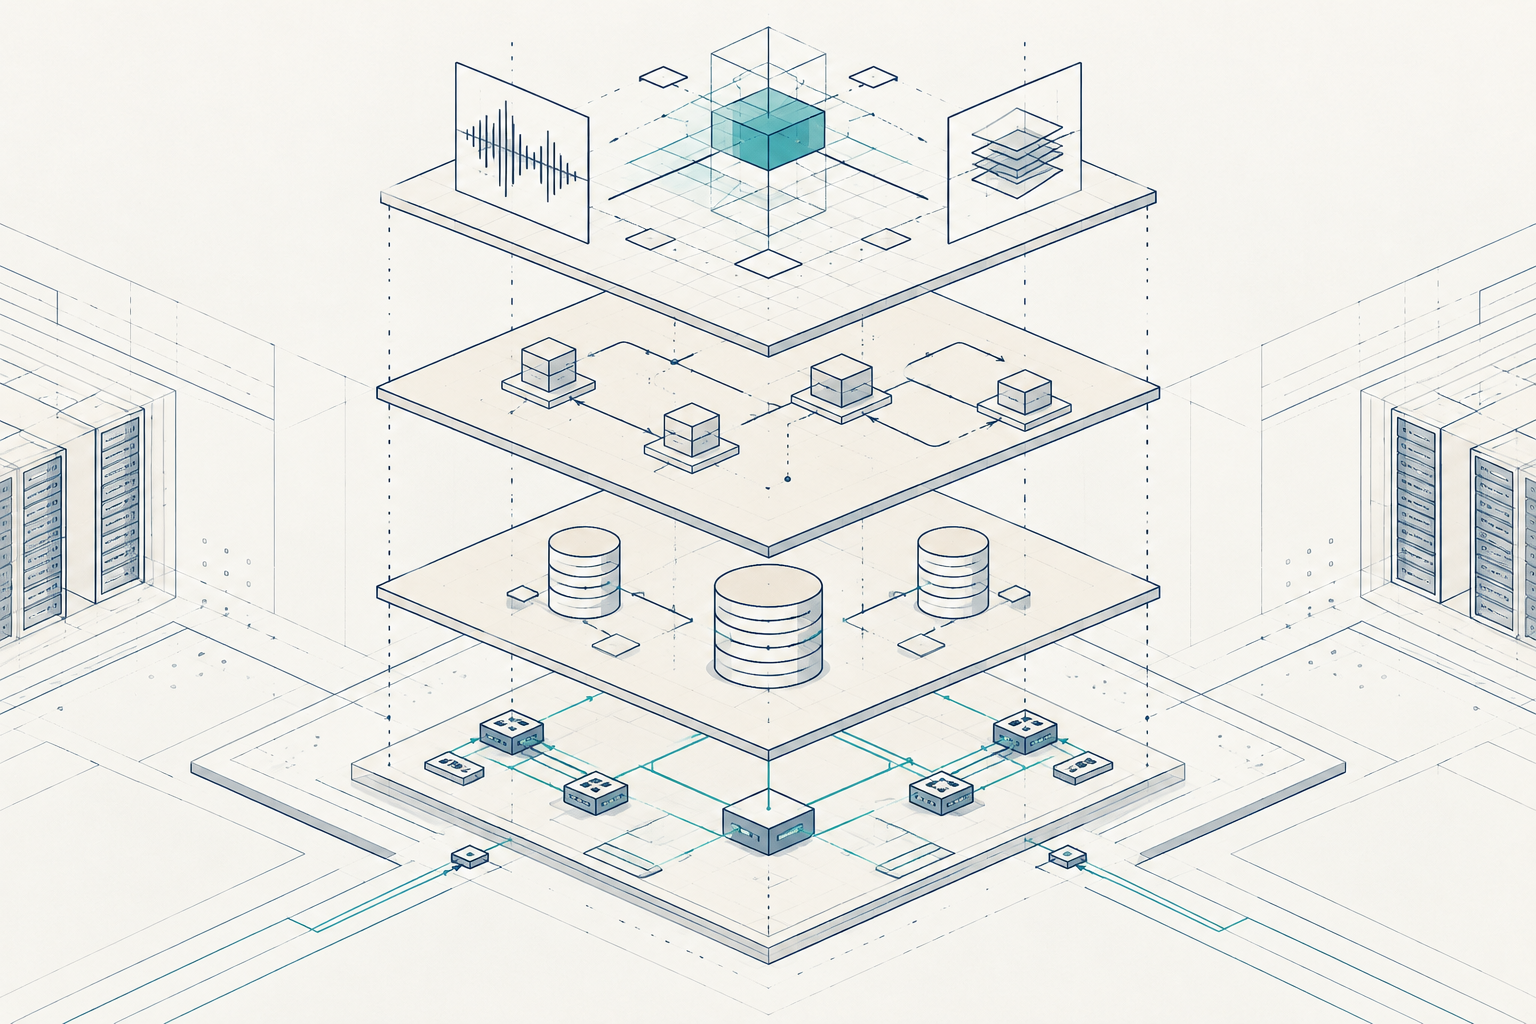
Agent Compute Changes Enterprise Infrastructure Planning
Google’s Agent Compute Engine announcement puts agent execution on the infrastructure agenda. A practical checklist separates inference, runtime, storage and network capacity.
10 min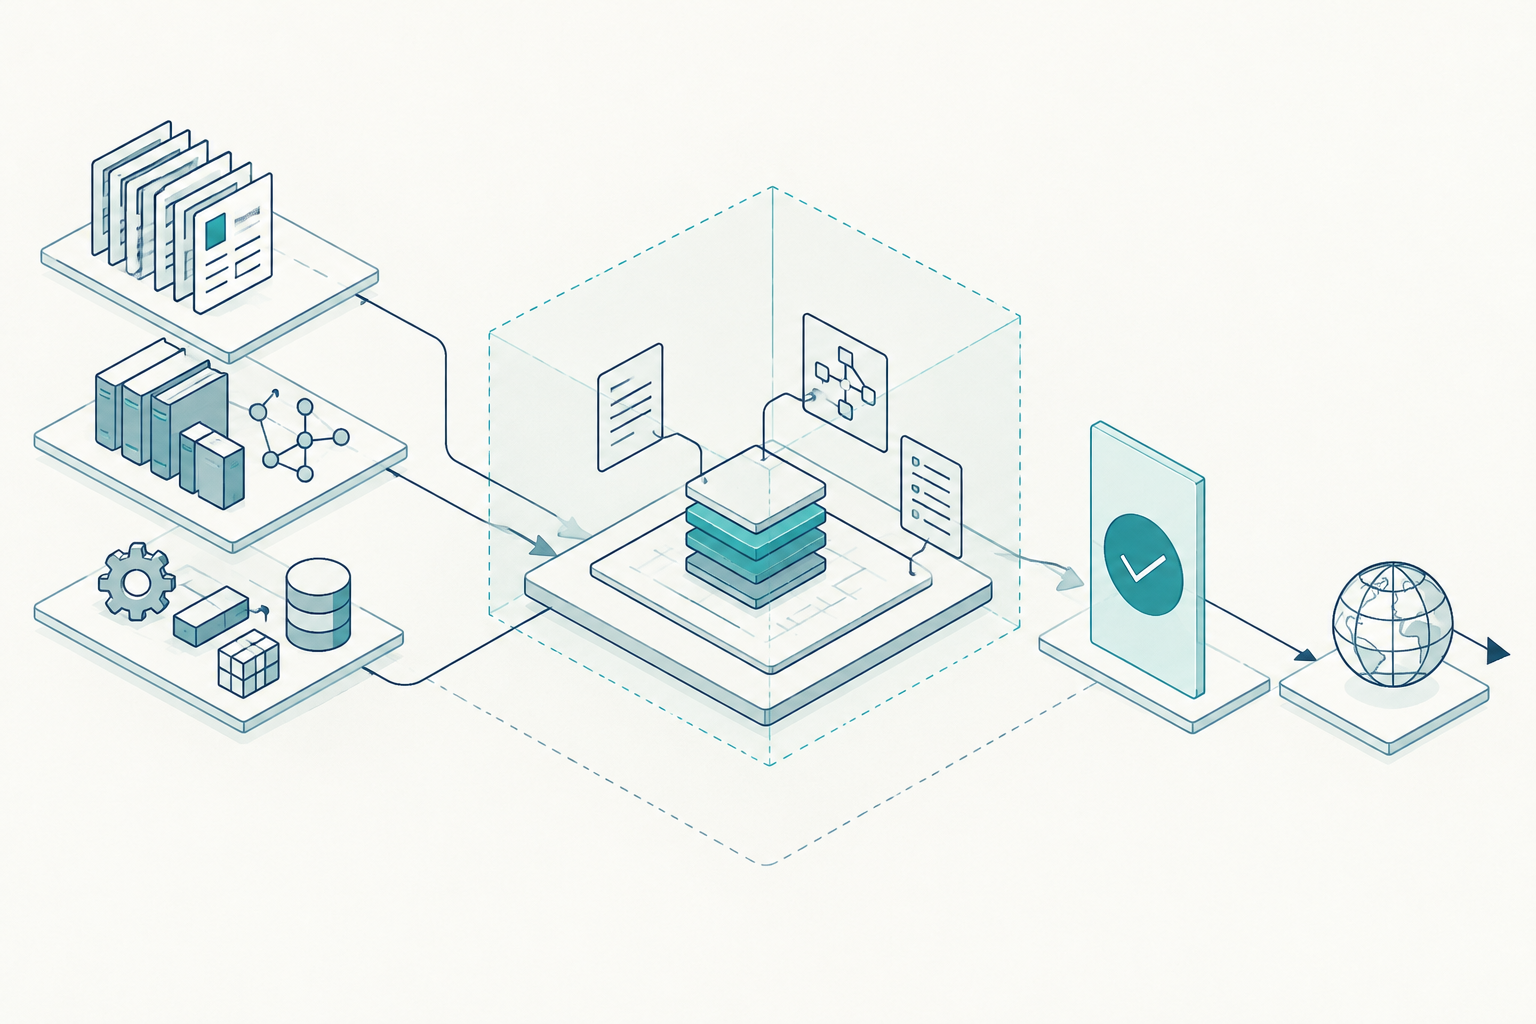
Composio Firewall puts employee AI task boundaries in focus
Composio’s Firewall announcement raises a practical question: how should organizations define the information, tools and escalation paths allowed for each employee AI task?
10 min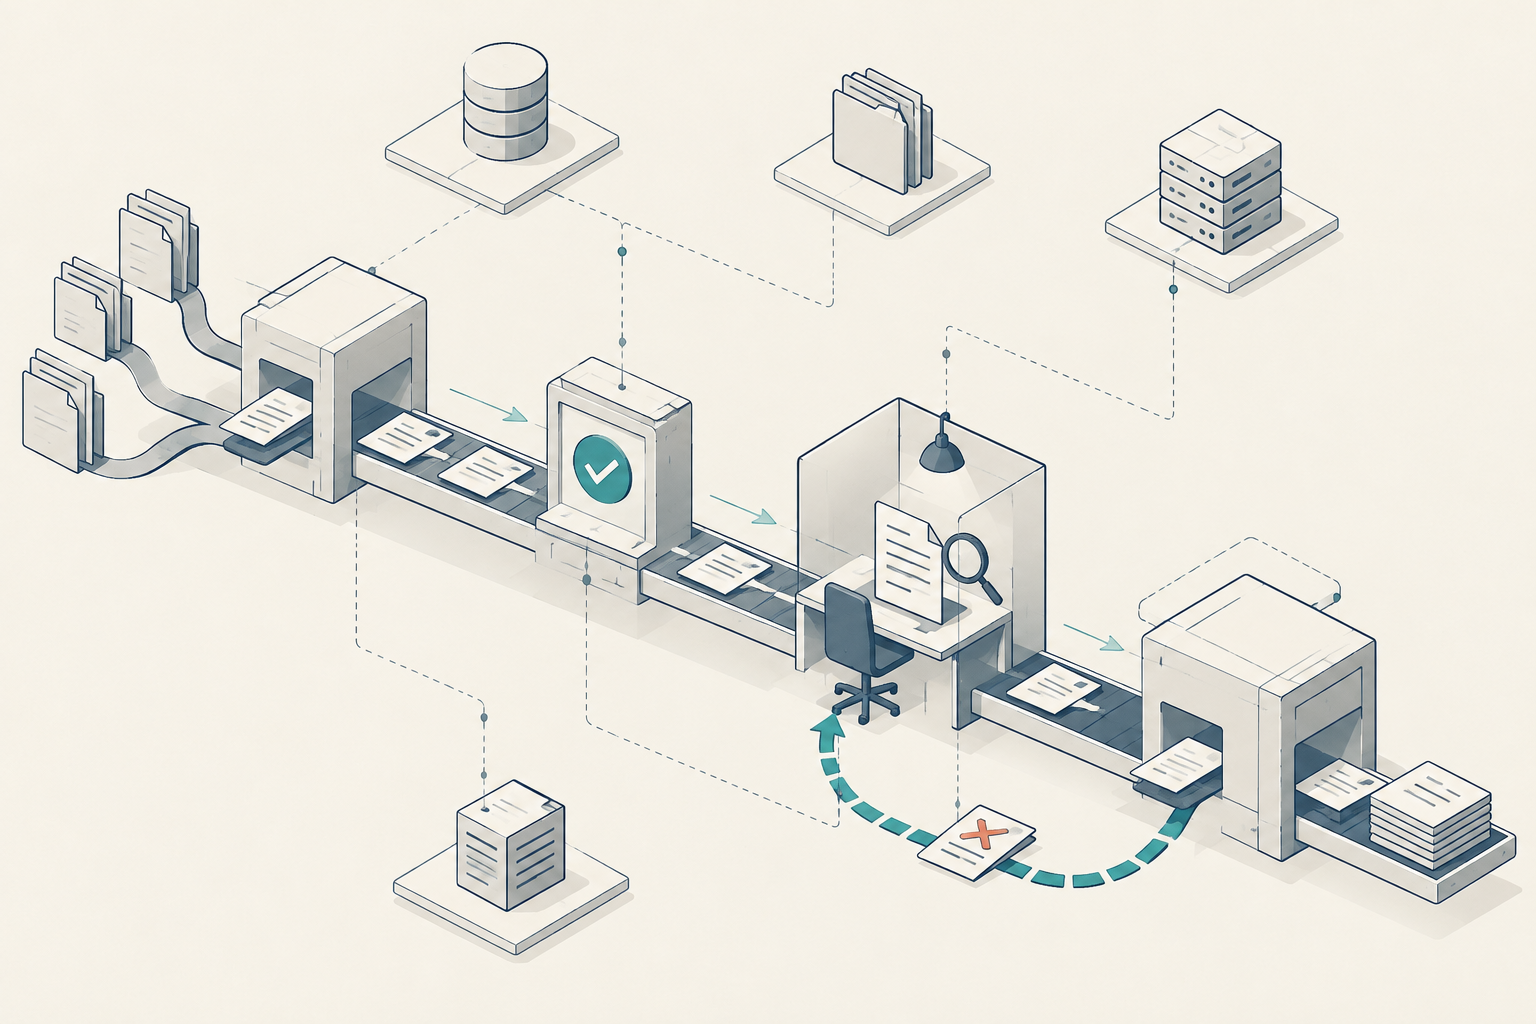
FinBursa’s launch puts enterprise handoffs under scrutiny
FinBursa’s platform launch raises a practical question: which enterprise handoffs should become connected workflows? A guide to bounded pilots, exceptions and measuring manual rework.
10 min
INVE’s GCC expansion puts event portfolio control in focus
INVE’s reported $300,000 funding highlights a scaling challenge for GCC event operators: shared intake, clear task ownership and portfolio reviews that lead to decisions.
10 min
The operational cost of a 510 GB DeepSeek refresh
A reported 510 GB DeepSeek checkpoint raises practical questions about staging, rollback and task costs across Clastiq infrastructure, Radon workflows and Radon Mini workspaces.
10 min
Janas puts SSD traffic on the inference tenancy checklist
Janas’s October 13 showcase raises an operator question: when does streaming experts from SSD make private inference viable, and when does it disrupt other tenants?
10 min
Apple’s Minions and the Limits of Office GPU Overflow
Idle office machines could absorb some batch inference, but leases, endpoint trust and transfer costs decide whether they actually relieve a busy GPU rack.
10 min
Inferock’s launch puts failed calls in GPU service economics
Inferock’s failed-call credit claim raises a practical question: how should GPU operators reconcile token bills, retries and capacity consumed by requests that never complete?
10 min
Replit’s Default Switch and the Cost of Local Inference
Changing model defaults reset the API alternative. Small GPU operators need task-level costs, residency-aware routing and a utilisation threshold before committing local capacity.
9 min
JustAd’s $5 Million Signal for Shared AI Capacity
A regional funding announcement is a reason to test demand, not buy GPUs. Here is a quarter-rack capacity and break-even design for shared campaign-analysis services.
10 min
Qwen’s Eight-Step Turbo Release Changes GPU Scheduling
Qwen-Image-2.1-Turbo makes eight-step generation a scheduling question: benchmark full-stack memory, accepted output and queue latency before changing GPU allocations.
10 min
Mellum2.1 needs more than an inference endpoint
A private coding-agent service needs GPU capacity, sandbox isolation and repository throughput. Size Mellum2.1 around completed engineering tasks, not token throughput alone.
9 min
Mistral Large 4’s Active Parameters Are Not a VRAM Budget
A trillion-parameter model needs a capacity decision, not an active-parameter shortcut. A fit-or-reject worksheet for GPU estates planning around Mistral Large 4’s preview.
10 min
AI Funding Is Not Bankable GPU Utilisation
Dealroom’s October funding release and Lambda’s reported fundraising point to capital concentration. GPU operators need contracts, deposits and workload evidence before adding capacity.
10 min
Lambda’s $4 Billion Push and Small GPU Operator Economics
A utilisation-sensitive model for quarter-rack to multi-rack GPU estates, and where managed private inference can justify a premium over commodity rental.
10 min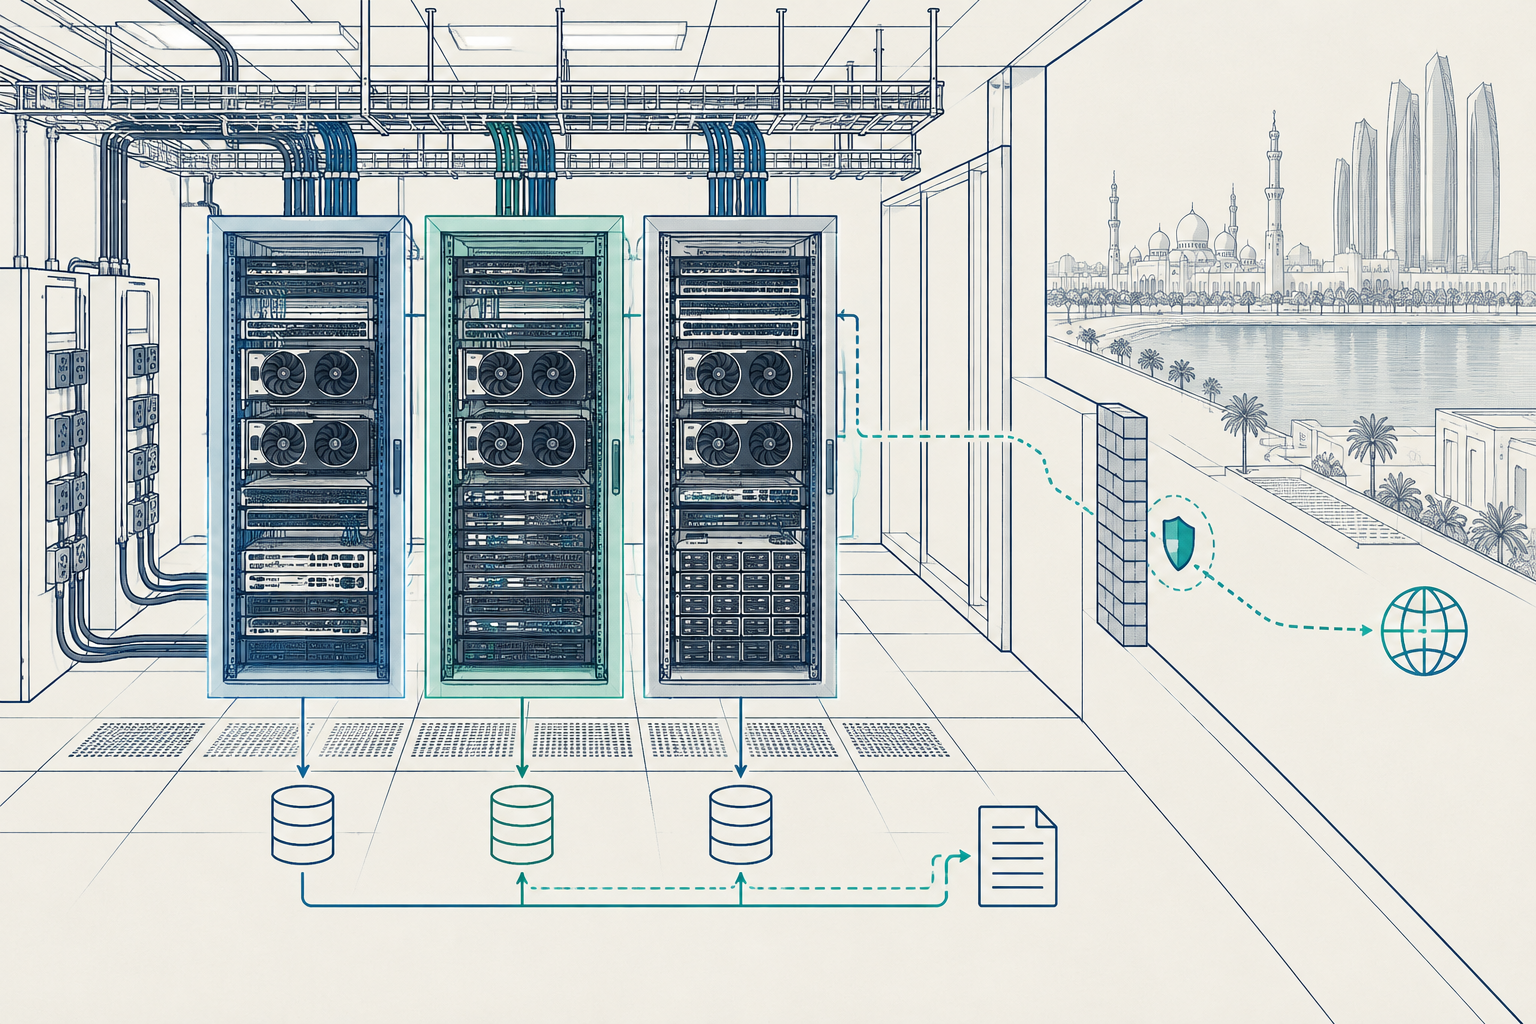
Jean 1001 and the Small-GPU Sovereignty Test
MetisJean’s Abu Dhabi announcement sets up an operator’s test: prove local execution, tenant isolation and recovery, then measure GPU-seconds per completed workflow.
10 min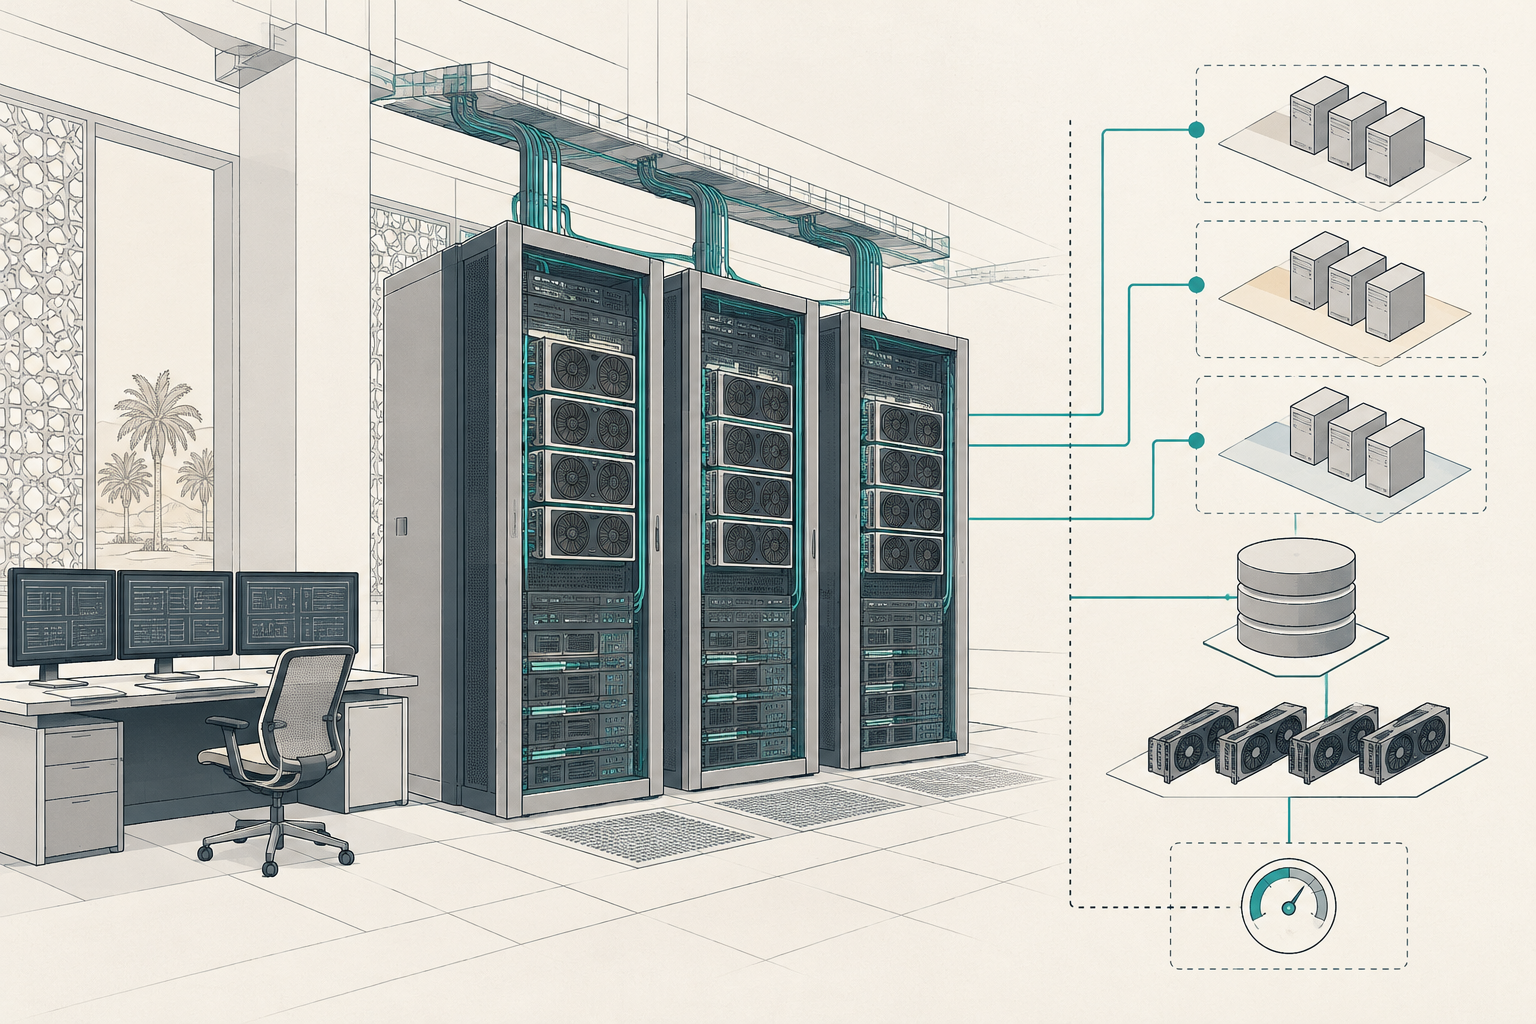
Echelon’s funding and the work of sharing Saudi GPU capacity
A blueprint for Saudi GPU operators supporting customer-specific AI deployments without building a separate, unmanageable cluster for every enterprise.
10 min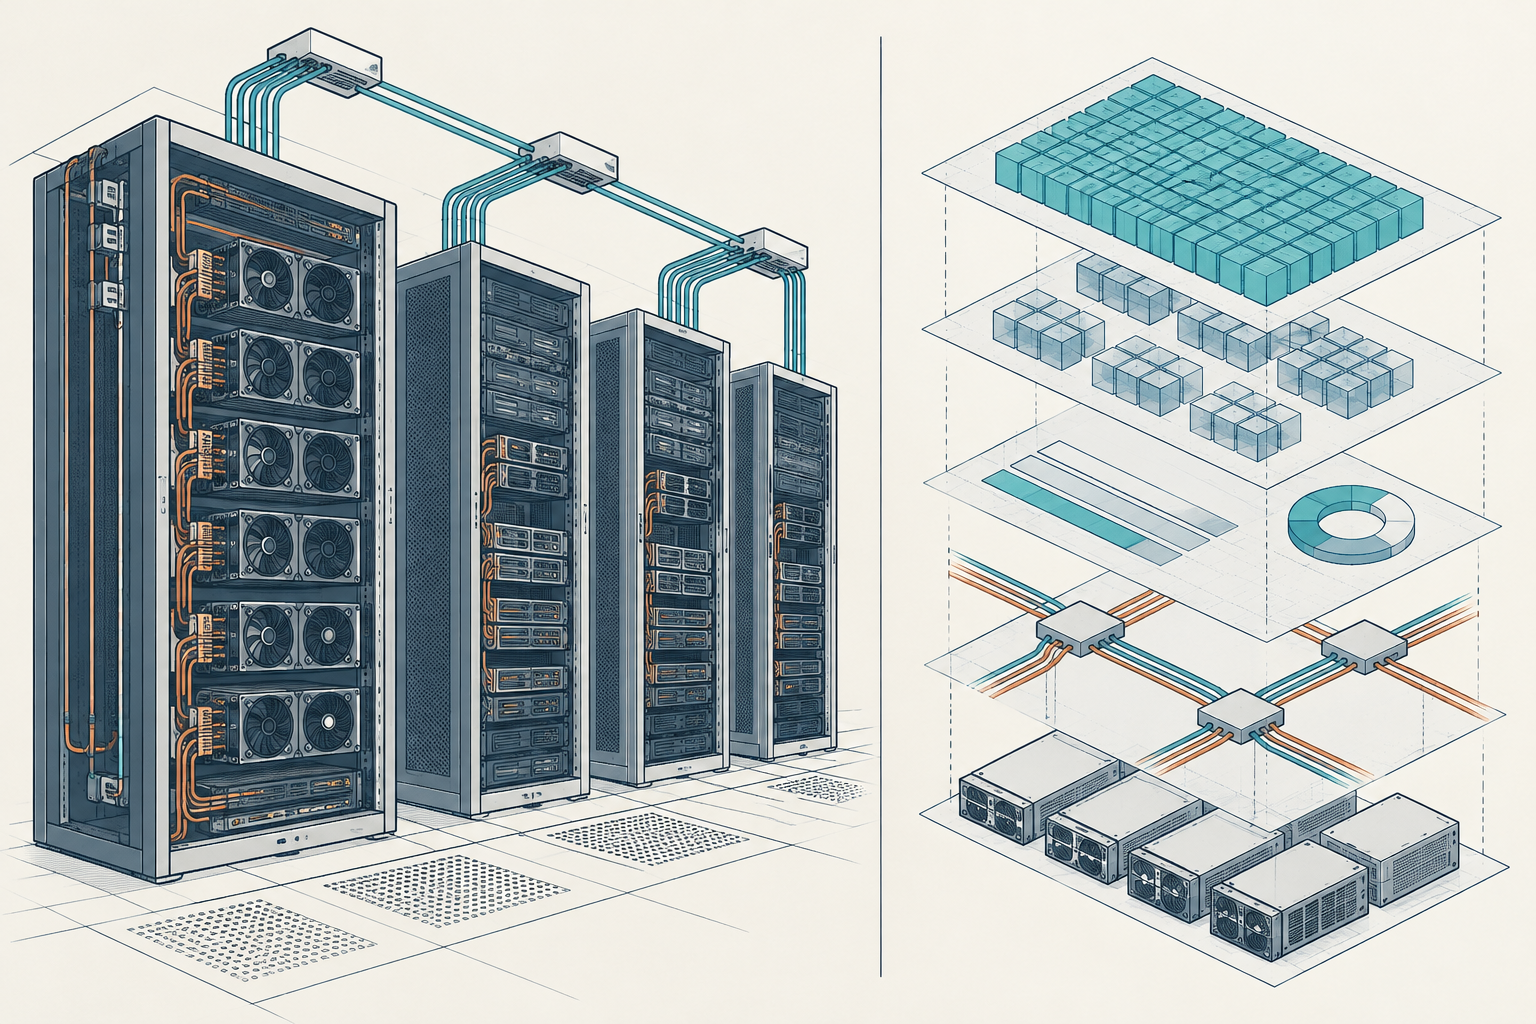
Naive-N0.5-Flash needs a deployment budget, not just GPUs
A 309B mixture-of-experts model still needs substantial weight memory. Budget KV cache, runtime headroom and fabric traffic before committing a small GPU estate.
10 min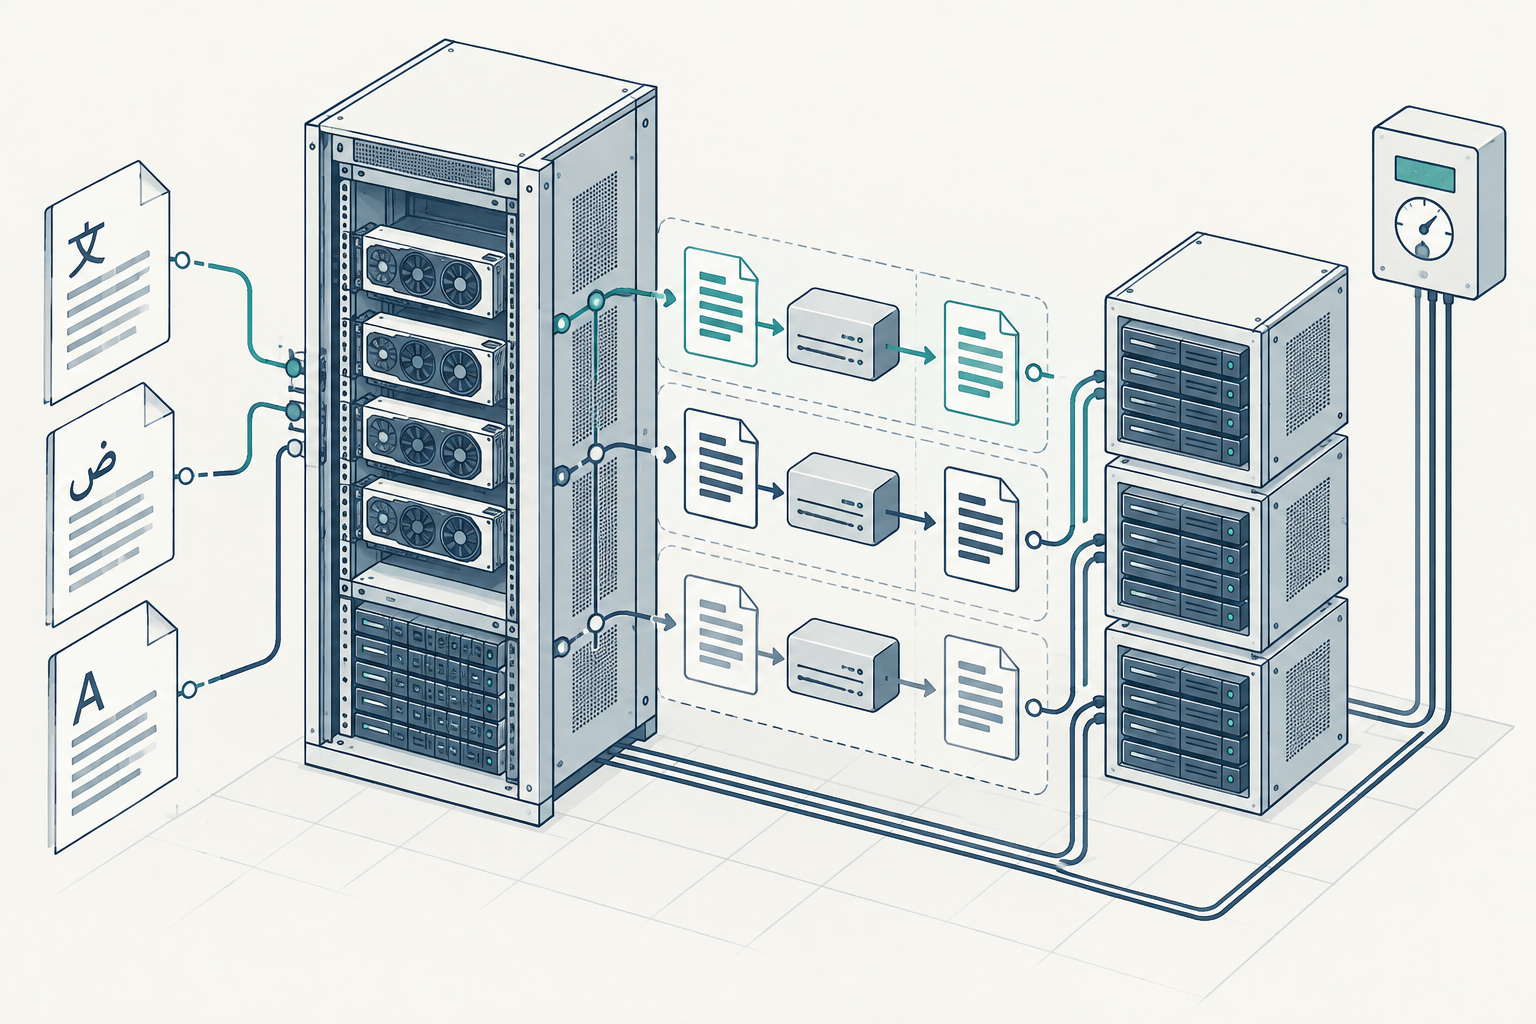
Index-Translate puts local translation capacity to the test
Bilibili’s translation models offer a local serving option. Operators still need to validate language quality, runtime compatibility and document economics on their existing GPUs.
10 min
OpenStack Hibiscus and the Small GPU Cloud Decision
Hibiscus puts trusted infrastructure and AI workloads in focus. For a small GPU estate, the decision turns on tenant isolation, hardware support and recoverable operations.
10 min
CoreWeave’s agenda becomes a small-cluster acceptance test
CoreWeave Fully Connected’s September–October 2026 agenda frames a practical question: how much reliable inference can a small GPU estate deliver within its power budget?
10 min
Sharon AI’s $356m facility puts billable GPU-hours first
GPU-backed finance does not make idle capacity productive. A worked operating worksheet shows how smaller estates can connect reservations, metering, power and tenancy to collected revenue.
10 min
Maven’s UAE Investment Signal and the GPU Estate Behind Robotics
UAE participation in Maven’s Series A points to an infrastructure question: how small GCC GPU estates can support robotics development without disrupting inference.
10 min
Aligator’s $1.2m round and the quarter-rack GPU service
A Qatar funding signal raises an operator question: how do you share a small GPU estate between PR batch jobs and interactive agents without losing isolation or predictable service?
10 min
MiMo-V2.6 deployment starts with total memory
Xiaomi’s MiMo-V2.6 release puts checkpoint residency, KV cache and serving compatibility ahead of active parameter counts for operators planning a few racks of inference.
10 min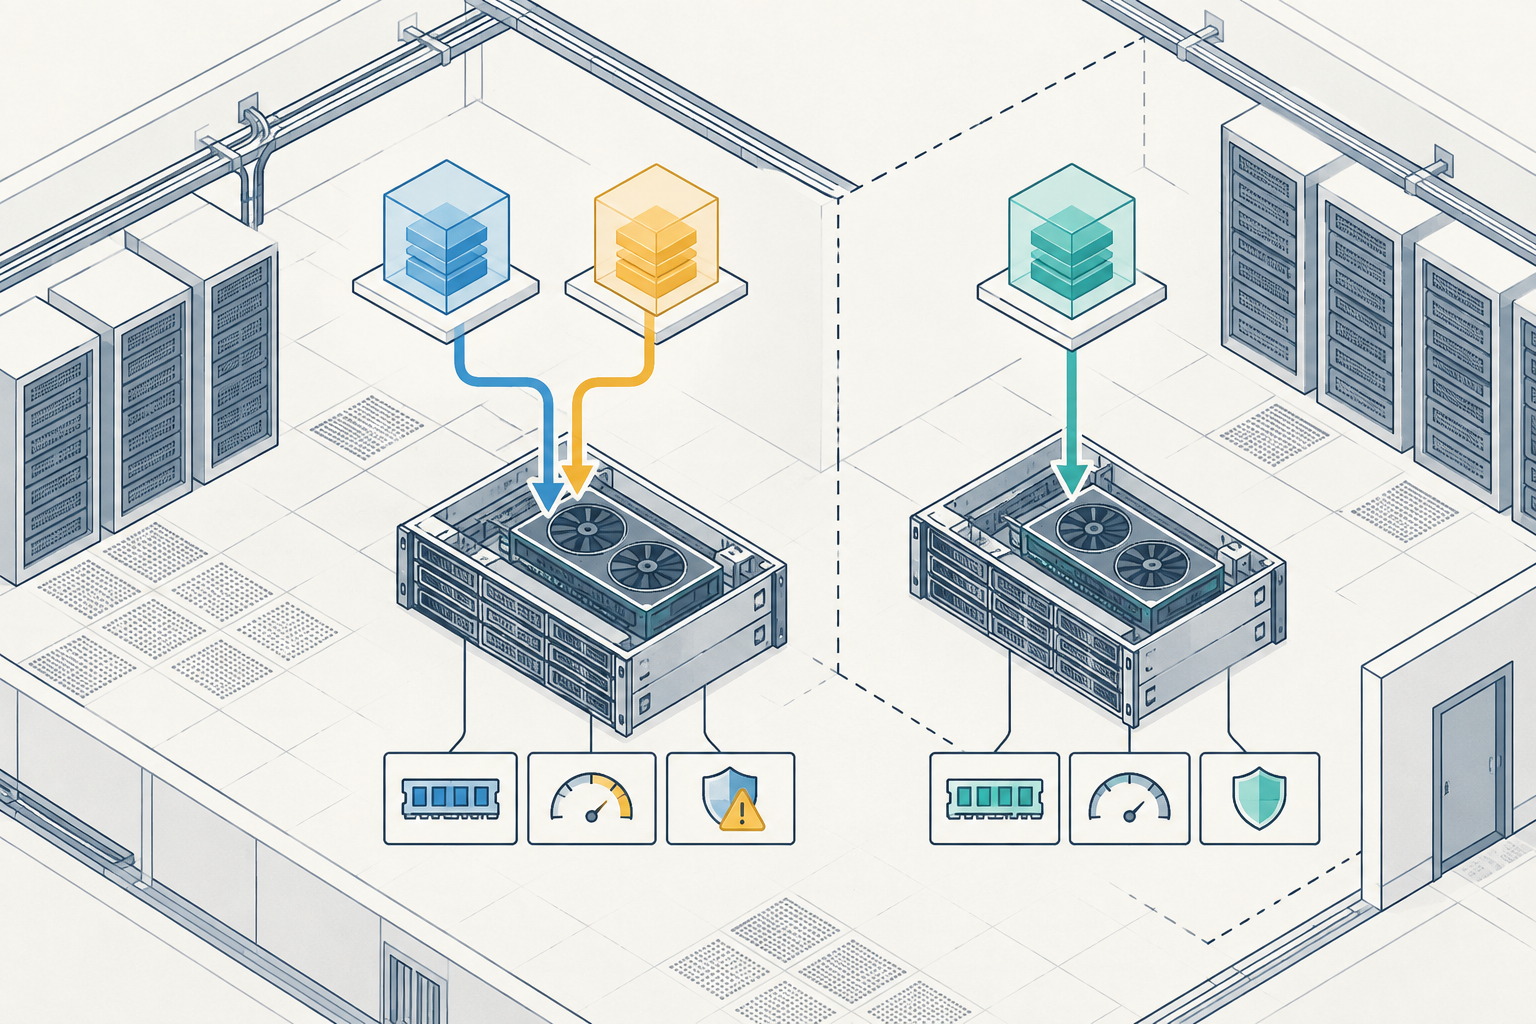
Virtio-nvgpu needs an isolation lab, not production tenants
Virtio-nvgpu surfaced on Hacker News with its planned isolation component still unimplemented. Test tenant boundaries, fault propagation and accounting before considering shared inference.
10 min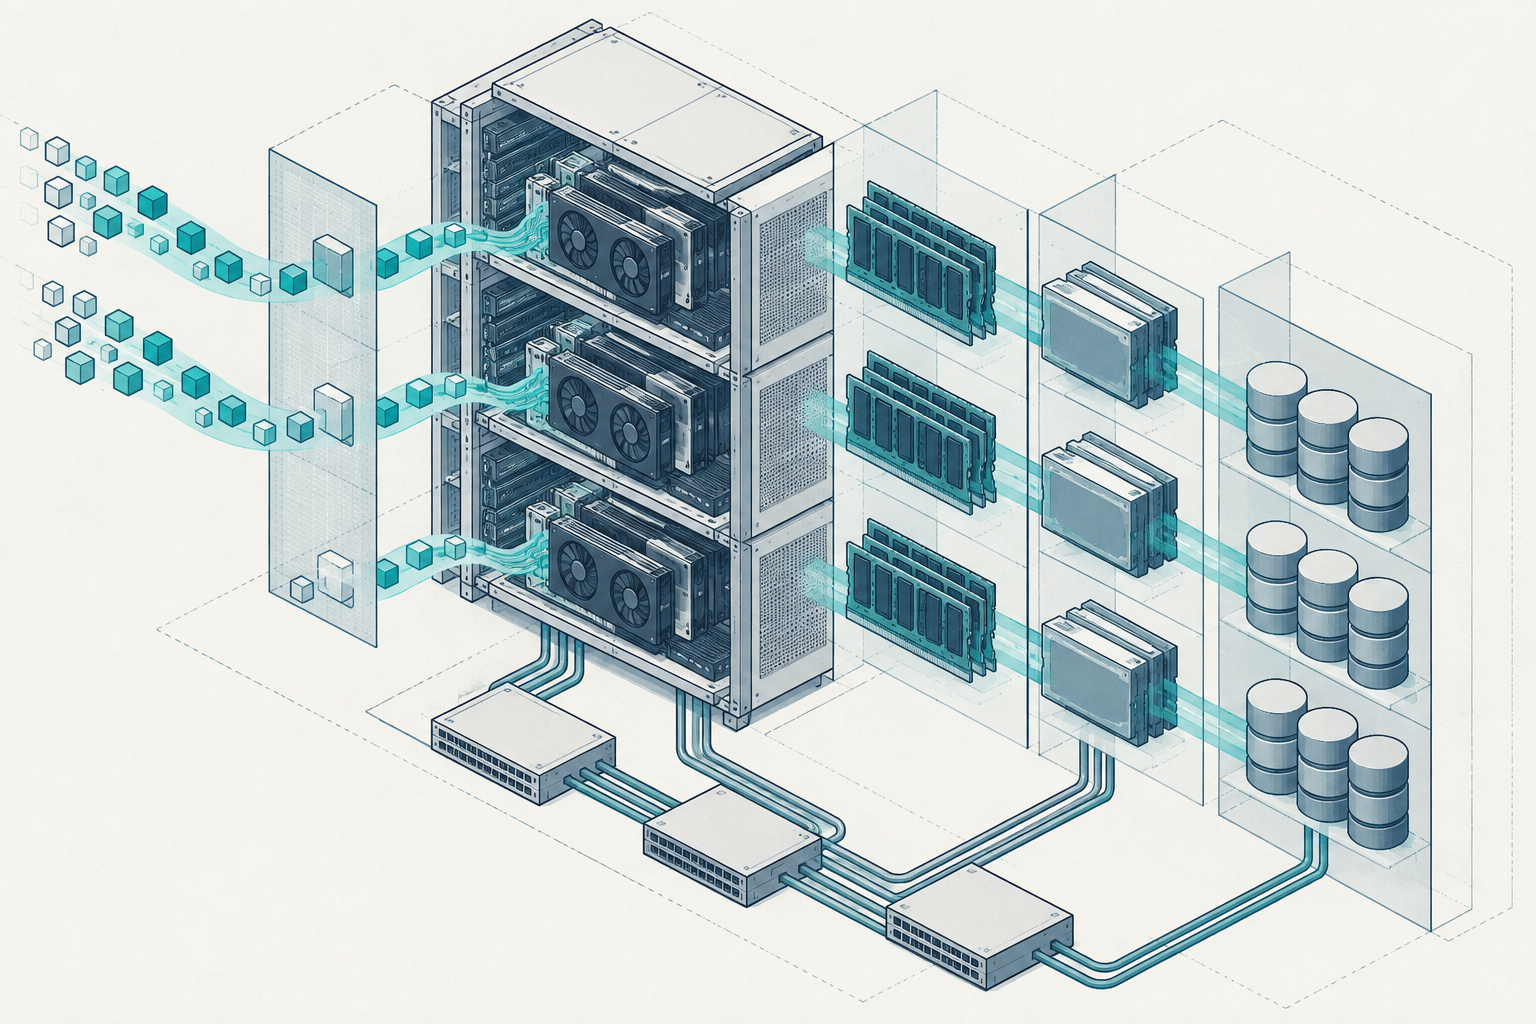
SGLang v0.5.20: test serving efficiency before buying GPUs
Test SGLang v0.5.20 against Arabic enterprise workloads, cache isolation and storage limits before turning an inference queue into a GPU purchase order.
10 min
Crusoe’s Boom exit puts GPU power readiness first
A cancelled turbine plan is a reminder to validate energised power, cooling and commissioning before buying GPUs. Here is a readiness checklist and an idle-capacity cost model.
10 min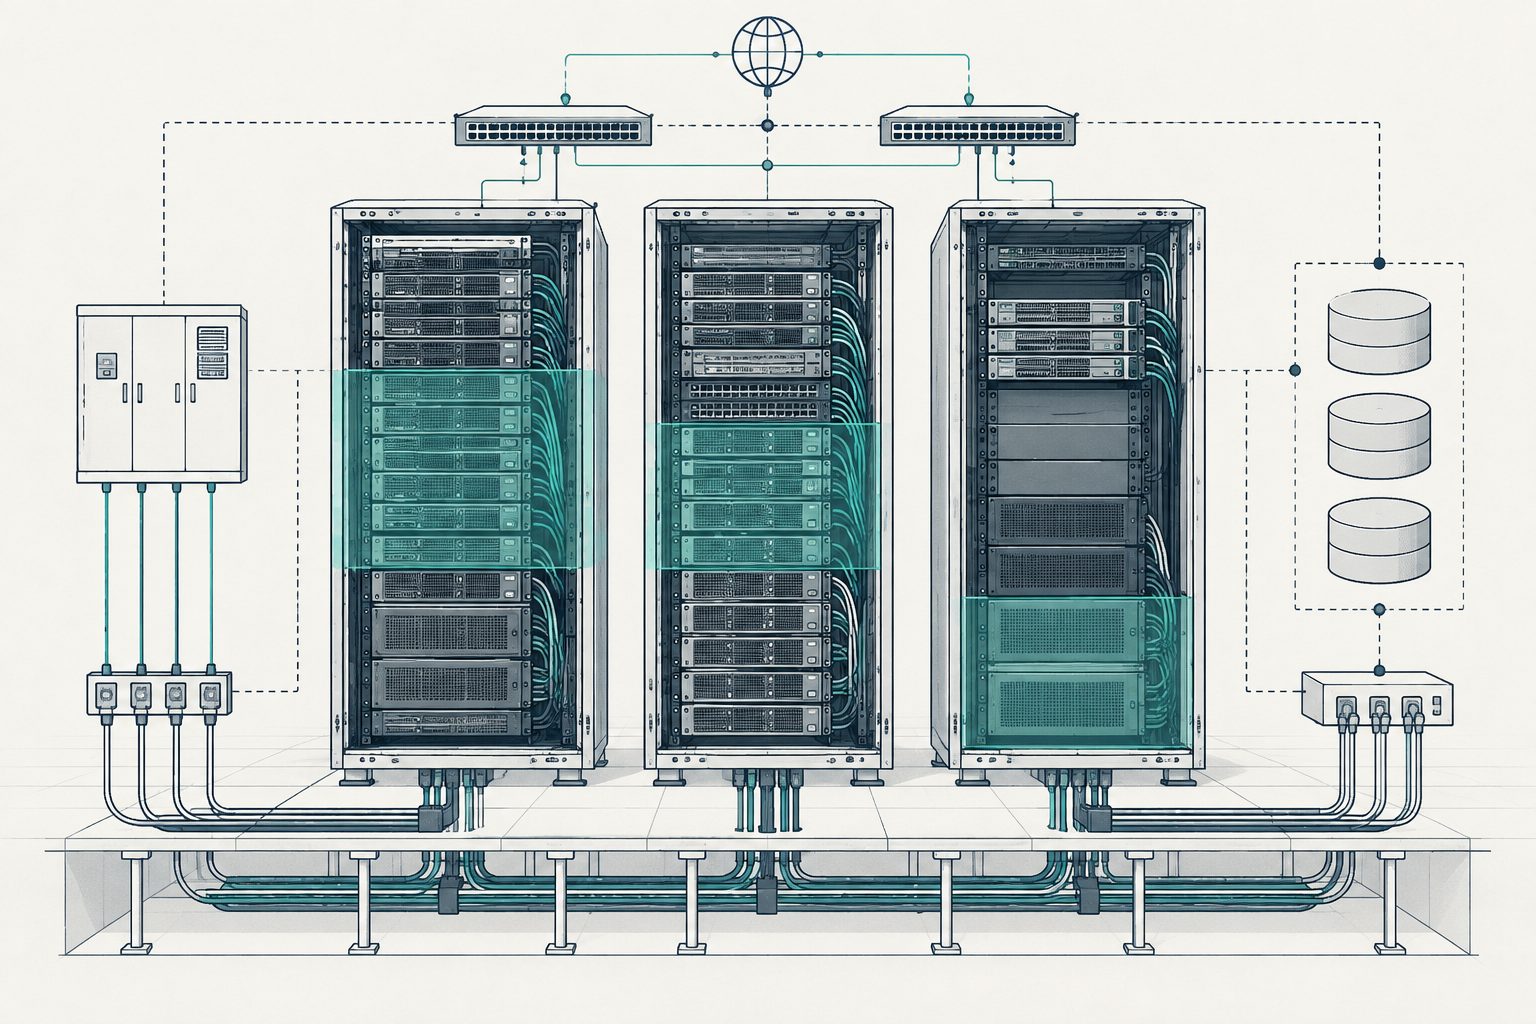
Akamai–Anthropic and the Cost of Reserving GPU Capacity
Dedicated compute contracts can stabilise a small GPU estate—or block its best customers. How to set commitments, activation gates, maintenance reserves and metering before selling capacity.
10 min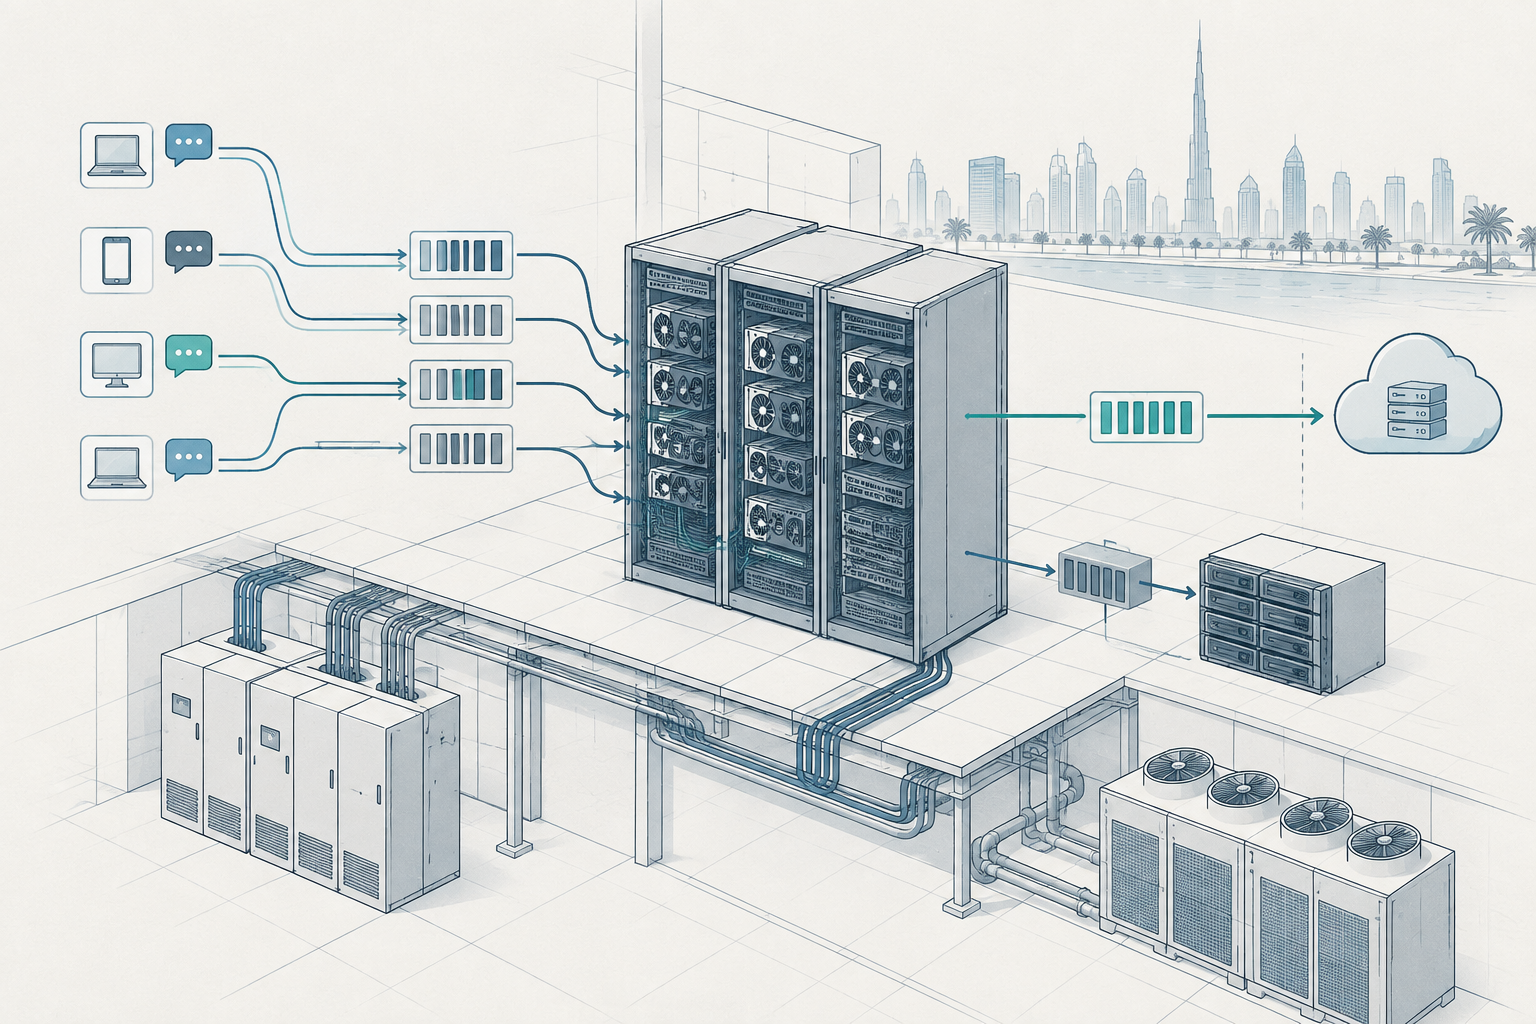
Sizing Local Inference for Dubai’s Conversational AI Demand
BroadNet’s Dubai demonstration is a demand signal, not an on-prem launch. Here is how GCC operators can test burst capacity, tenant isolation and interaction costs on their own GPUs.
9 min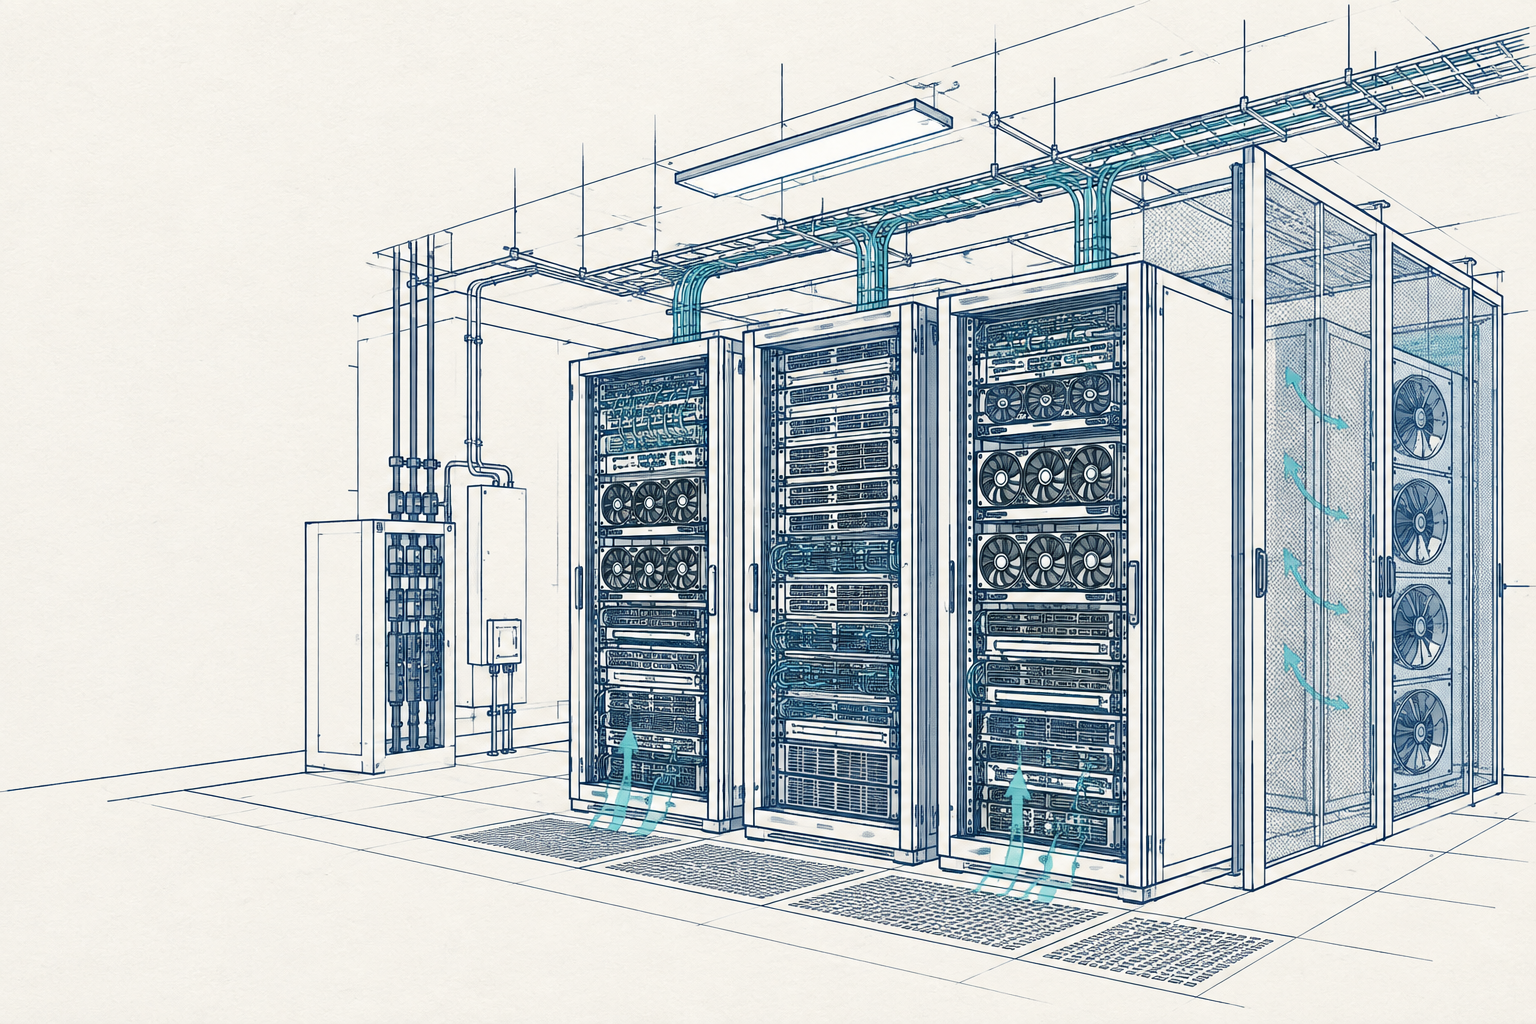
After Nscale’s $3.36B Raise, GCC GPU Operators Need Paid Load
Nscale’s financing raises the stakes for small GCC GPU estates. Compete through paid utilisation, capacity commitments and costed sovereign services—not GPU-hour discounts.
10 min
nvidia-smi for cluster operators: from CLI to automated fleet telemetry
A field guide to utilization, power and thermals across racks — and where manual polling stops scaling.
12 min