An announcement, not an acceptance result
Wamda’s October 6, 2026 report described MetisJean’s planned Jean 1001 launch and demonstration at Ai Everything Abu Dhabi. The proposition included execution inside customer infrastructure and auditable actions. For enterprise operators, that changes the procurement conversation: instead of evaluating only a hosted assistant, they must evaluate software that will consume, control and leave records on infrastructure they operate.
The evidence boundary matters. This is one announcement source, with a signal weight of one. It establishes that the launch and demonstration were announced; it does not establish general availability, independently tested performance or successful disconnected operation. A token-reduction claim should remain a vendor claim until operators reproduce the relevant result against their own workflows.
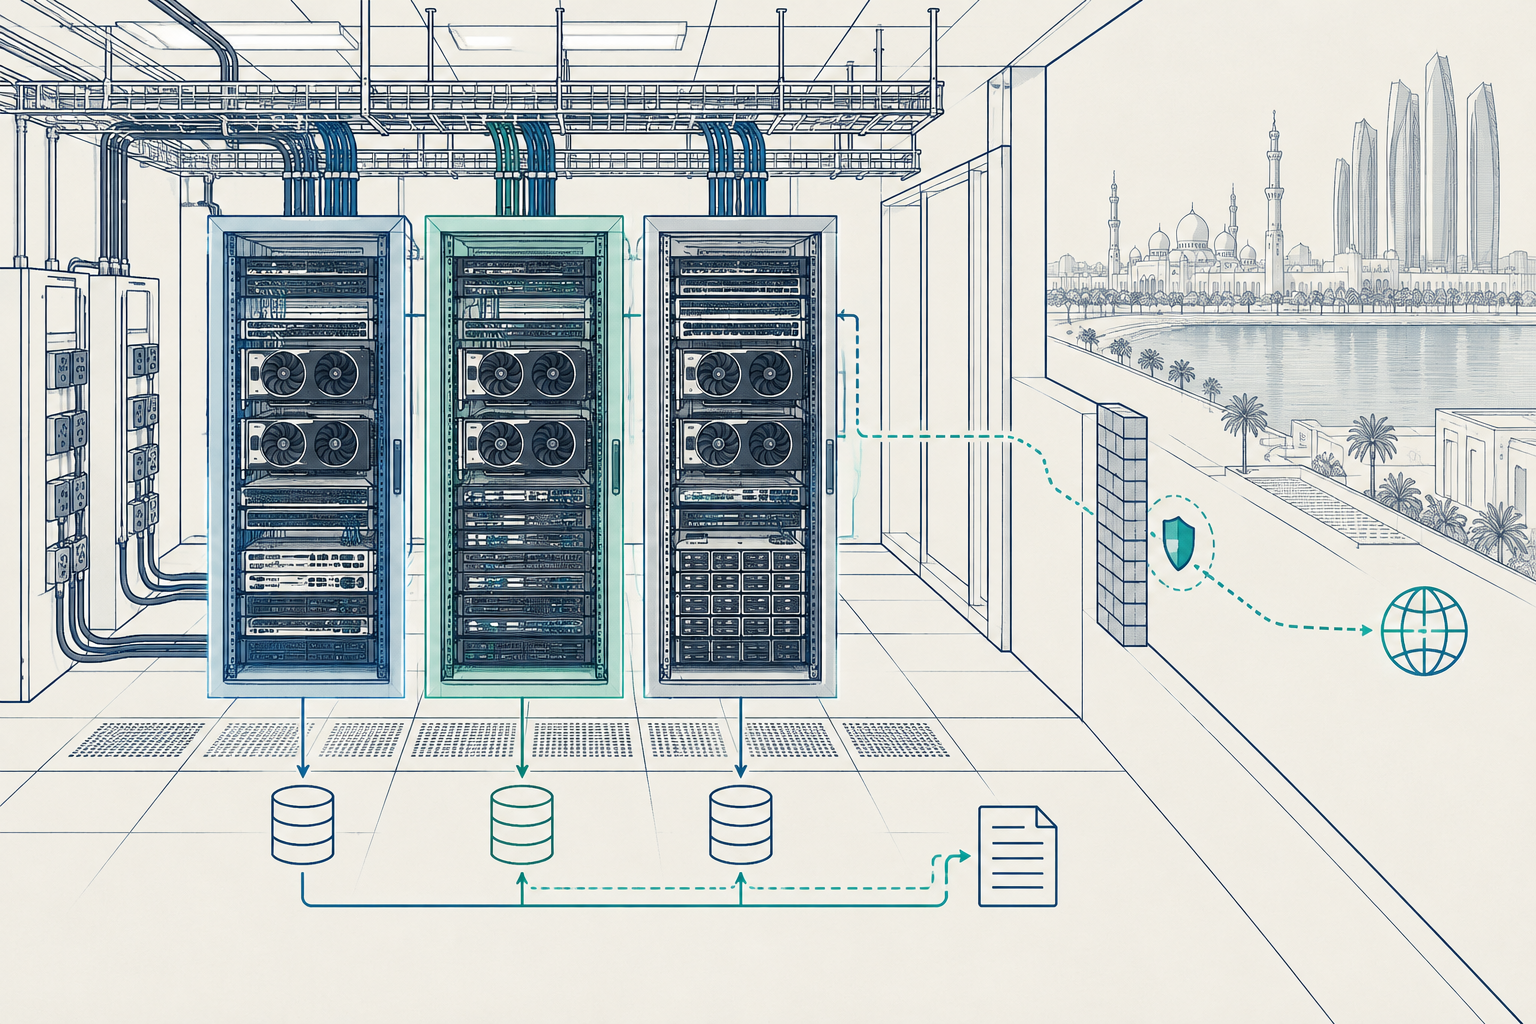
For a GCC enterprise with a quarter rack to a few racks, the question is therefore practical: can this class of system complete useful work within a defined local boundary without exhausting shared GPUs, weakening tenant separation or overwhelming audit storage? Jean 1001 is the news trigger. An infrastructure acceptance test is the appropriate response.
The bottleneck is shared capacity under policy
A small GPU estate rarely belongs to one application. Document processing, inference, model evaluation and VM tenants may share accelerators, CPU cores, network uplinks and storage. An agentic workflow adds bursts: retrieval, repeated inference, tool execution, retries and evidence capture. Average utilisation can look comfortable while queue latency and memory pressure make one department’s service unusable.
Local execution also transfers operational responsibility. The operator must host dependencies, retain evidence, enforce identity boundaries, allocate spare capacity and recover failed state. Restricting internet access can expose installation-time downloads or licensing checks that an ordinary demonstration never exercises. Adding auditability can turn a compute purchase into a storage and retention problem.
A system like Clastiq Orchestrator addresses the infrastructure side through bare-metal provisioning, Kubernetes and VM tenancy, GPU partitioning, Ceph storage, per-tenant metering and chargeback, and quota and policy engineering. These are mechanisms for establishing a controlled operating envelope, not proof that any particular application respects it. Application behaviour still needs measurement and acceptance evidence.
Define sovereignty as a testable boundary
Start with a written boundary rather than a label. Identify where prompts, source documents, embeddings, model weights, credentials, outputs and audit records may reside. Name the identities permitted to administer each layer. Specify whether support personnel may view diagnostic bundles and whether those bundles can cross national or organisational boundaries.
In Oman, the UAE and other GCC markets, an in-country server location is only one part of that decision. Procurement, sector requirements, contracts and organisational policies may impose different constraints. A remote control plane or external model endpoint can breach a customer’s intended boundary even when the GPU sits in its own building. Translate the applicable requirements into explicit controls with legal and security teams.
Then agree on observable pass conditions before a vendor demonstration. Use an isolated trial tenant and representative, non-production data. Record the application version, model hashes, infrastructure configuration and test time. Keep the resulting evidence with the acceptance decision so that a later model or dependency change can trigger a targeted retest.
| Test area | Exercise | Required evidence |
|---|---|---|
| Outbound access | Deny external traffic during installation and execution | Firewall logs, resolver logs, captured failure behaviour |
| Model dependencies | Rebuild from approved local artifacts | Manifest, hashes, startup and workflow results |
| Tenant separation | Attempt cross-tenant access and resource exhaustion | Denials, resource metrics, unaffected peer workload |
| Audit growth | Run a fixed workload with full tracing | Bytes per workflow, retention projection |
| Recovery | Interrupt a worker and restore state | Recovery time, reconciled actions, data-loss measurement |
Test outbound access beyond inference
Observe the full lifecycle: installation, startup, idle operation, inference, tool use, update checks and shutdown. Collect DNS and connection records at a boundary the application cannot modify. An inference-only packet trace can miss a package download during provisioning or an idle telemetry job hours later.
Apply default-deny egress and allow only named internal dependencies. Kubernetes NetworkPolicy can be one layer, provided the cluster’s network implementation enforces it. VM tenants need equivalent firewall controls. Host networking, management interfaces and storage networks require separate review; a namespace rule is not a complete air-gap design.
A minimal starting point for the trial namespace is:
apiVersion: networking.k8s.io/v1
kind: NetworkPolicy
metadata:
  name: deny-egress
  namespace: sovereignty-trial
spec:
  podSelector: {}
  policyTypes:
    - Egress
  egress: []
This blocks pod egress, including DNS and internal services, where supported. Add narrowly scoped policies for approved local endpoints, then verify enforcement with independent probes. Inspect all policies selecting those pods: another policy can add allowed traffic. Retest after restarts and upgrades. The pass condition is not merely “no packets observed”; required workflows must complete, or fail explicitly and safely, without silent fallback to an external service.
Make the model supply chain local
Request a dependency inventory covering model weights, tokenizers, embedding models, rerankers, runtime libraries, container images, tool connectors and licence validation. Ask which components are bundled, which are fetched lazily and which require periodic renewal. A locally hosted interface can still depend on an external embedding service or a remote entitlement check.
Prove rebuildability from approved local repositories. Start a clean worker with empty caches and no internet route, then execute the acceptance workload. This distinguishes an actual disconnected deployment from a demonstration that succeeds because someone previously populated a cache. Verify signatures or hashes and retain the mapping between each workflow result and its deployed model version.
Air-gap operations also need an update procedure. Define how artifacts enter, who approves them, how malware scanning and integrity checks occur, and how rollback works. Clastiq Orchestrator’s air-gap deployment scope is relevant here, but the application supplier must still provide distributable artifacts and compatible licensing. Infrastructure cannot repair a dependency contract that requires continuous external access.
Separate tenants and constrain noisy neighbours
Treat application identity, storage access and accelerator allocation as separate isolation problems. Give each tenant distinct service identities, secrets, storage permissions and network policy. Test attempted access to another tenant’s object paths, volumes, logs and model endpoints. Include backup and support access in the same review: those channels often have broader privileges than runtime services.
GPU partitioning helps allocate scarce capacity, but its isolation properties depend on hardware and runtime support. Use supported hardware partitions where suitable; otherwise evaluate whole-device assignment or scheduling boundaries. Do not represent time-sharing as equivalent to a hardware security boundary. Kubernetes namespaces alone are also insufficient evidence of strong multitenant isolation.
Run one tenant’s accepted workflow while another drives memory pressure, request bursts and storage writes. Measure the first tenant’s completion rate and tail latency. Clastiq Orchestrator can provide tenancy, partitioning and policy controls across Kubernetes and VM workloads; operators must select a supported isolation design and prove it under contention. Where risk demands stronger separation, reserve capacity or isolate hosts rather than optimising every accelerator for occupancy.
Benchmark completed work, not token savings
Token counts describe only part of a workflow. Fewer generated tokens may accompany more retrieval calls, slower model execution, repeated tool failures or lower-quality outputs. Compare systems using the same input set, completion criteria, model-quality threshold, concurrency and retry policy. Include failed attempts in the resource total rather than charging only the final successful attempt.
Define GPU-seconds per completed workflow as total accelerator time attributable to the test divided by accepted completions. On exclusive devices, allocation time is straightforward to meter. On shared devices, state whether the numerator uses partition allocation, scheduler reservation or measured active time. Do not combine unlike measurements into a single efficiency claim. Report elapsed latency, quality failures and queue time alongside it.
Consider an illustrative estate with eight GPUs over a 30-day month. Its gross capacity is 8 × 24 × 30 = 5,760 GPU-hours. Suppose maintenance, recovery headroom and other tenants leave 60% available to this service: 3,456 GPU-hours. That is an allocation assumption, not a measured utilisation result or a Clastiq benchmark.
In trial A, 10,000 accepted workflows consume 600 GPU-hours, including unsuccessful attempts. That equals 2,160,000 GPU-seconds, or 216 GPU-seconds per accepted workflow. Trial B consumes 450 GPU-hours for the same accepted output set: 162 GPU-seconds per workflow. The measured reduction is 25%, regardless of how much the vendor says token counts fell.
At an illustrative internal rate of $2.40 per GPU-hour, accelerator chargeback falls from $1,440 to $1,080, or from $0.144 to $0.108 per completed workflow. That is a $360 difference for 10,000 completions. CPU, storage, networking, licences and support remain additional costs unless the rate explicitly includes them. At unchanged performance, the 3,456-hour budget supports 57,600 trial-A workflows or 76,800 trial-B workflows; production contention can reduce both figures.
Budget audit storage before approving retention
Auditable actions require an evidence design, not simply verbose logs. Capture actor identity, authorisation decision, model and tool version, action request, outcome, timestamps and correlation identifiers. Decide whether full prompts and tool payloads are necessary. They can contain sensitive information, so minimise or redact content according to the organisation’s evidence requirements.
Measure stored bytes after compression and indexing, not raw text alone. Suppose 20,000 completed workflows per day create 1.5 MB of retained evidence each, including their associated retries. Using decimal units, that is 30 GB per day and 2.7 TB over 90 days. Three replicated copies require about 8.1 TB before metadata, indexes, backups and free-space headroom.
Ceph gives the operator a local storage layer, but pool configuration determines usable capacity and failure behaviour. Audit traffic must not crowd out VM disks, retrieval indexes or recovery operations. Set tenant storage quotas, monitor growth and define what happens when evidence cannot be committed. For sensitive actions, fail-closed behaviour may be appropriate; agree that policy before a full volume stops production unexpectedly.
Recover actions, not just containers
A restarted pod does not prove workflow recovery. Interrupt a worker after it submits a tool action but before it records success. Then determine whether restart duplicates the action, loses it or reconciles it correctly. Use idempotency keys where supported and durable checkpoints for application state. Test a failed external tool as well as failed local compute.
Set recovery-time and recovery-point objectives for model services, workflow state and audit evidence separately. Model weights may be reproducible while an unrecorded approval is not. Restore into an isolated environment and reconcile accepted workflows, pending actions and audit identifiers. Document any manual steps and the identities authorised to perform them.
On a small estate, recovery competes with production for the same disks, network and power. Test a storage recovery event while representative tenants are active. Preserve enough capacity for that condition rather than selling every nominal GPU-hour. A spare scheduling slot is operational headroom only if the associated CPU, memory and storage bandwidth also exist.
Turn acceptance into enforceable operating policy
After the trial, convert findings into admission rules and budgets. Assign each tenant accelerator limits, maximum concurrency, storage quotas and an agreed chargeback basis. Bound workflow retries and tool execution time so a malformed task cannot consume an entire overnight allocation. Distinguish reserved capacity from burst capacity, and show both in metering reports.
Power is another admission constraint. Measure host and rack draw during the workload, not only accelerator telemetry. Check circuits, cooling limits and the power needed during recovery. In GCC facilities, assess the site’s actual cooling capacity and seasonal operating constraints rather than assuming a GPU nameplate rating predicts rack-level demand. Schedule heavy batch work around available capacity where service commitments permit.
Cognition-AI is based in Muscat, Oman, and Clastiq Orchestrator is its first official product. Its scope places these controls on operator-owned infrastructure, with human-led local support. That proximity can help organise deployment and incident work; it does not replace an acceptance record, a tested runbook or a written support boundary.
What to do this week
- Request Jean 1001’s deployment manifest, dependency inventory, licensing behaviour and audit schema. Mark unavailable evidence as an open acceptance item, not an assumed capability.
- Build a trial tenant with default-deny outbound access. Capture network evidence through installation, cold startup, representative workflows and restart, using approved non-production data.
- Run a fixed workflow corpus with a quality threshold. Record accepted completions, failures, retries, GPU-seconds, queue latency and total elapsed time; keep token counts as a secondary metric.
- Test cross-tenant access and contention while measuring a peer tenant. Record which boundaries rely on namespaces, VMs, hardware partitions or dedicated hosts.
- Project audit capacity from measured bytes per workflow, then interrupt and restore a workflow. Confirm reconciliation, available recovery headroom and the behaviour when audit storage is unavailable.
Clastiq Orchestrator runs this infrastructure on the operator’s own hardware: request a demo.