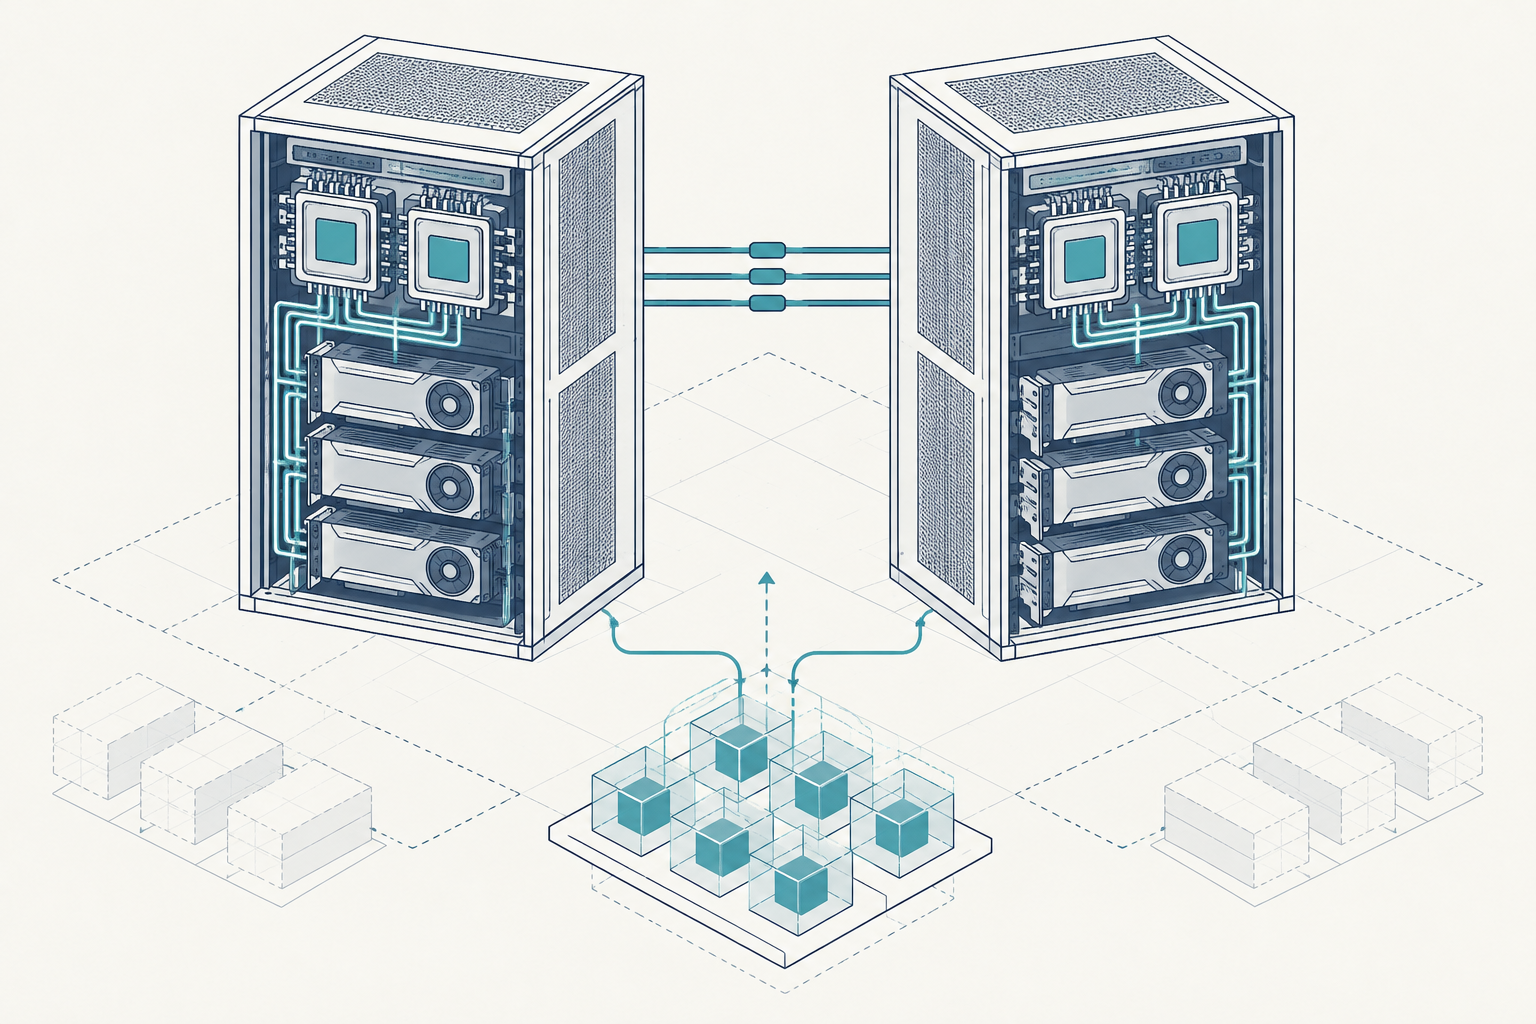
HAMi puts placement beyond the GPU count
HAMi v2.11.0, released November 4, 2026, lists GPU/CPU NUMA alignment, PodGroup support and scheduling-policy combinations. These changes put three operational questions alongside accelerator availability: which CPUs feed the GPU, whether related workers can be admitted together, and how placement preferences interact. For operators running distributed workloads, a cluster-wide total of free GPUs is only the beginning of a scheduling decision.
The release is the news peg, not proof that every deployment now delivers topology-aware, all-or-nothing execution. Operators should read the v2.11.0 release notes, then verify the relevant configuration, dependencies and semantics in their installed version. In particular, PodGroup support should not be treated as a blanket guarantee that every worker starts simultaneously or that failed launches are automatically rolled back.
The practical issue is straightforward: aggregate capacity can exist without a feasible placement. Eight available GPU allocations spread across incompatible nodes may not satisfy an eight-worker job. Even when placement succeeds, remote CPU memory access, network contention or slow shared storage can leave expensive accelerators waiting. This makes orchestration across resources more important than a GPU-only availability dashboard.
Free capacity is not runnable capacity
A scheduler works with constraints, not just totals. A workload may need a particular accelerator type, minimum device memory, CPU and host-memory reservations, approved node labels, a compatible runtime and access to its dataset. Distributed workers add relationships: enough members must become ready, communicate and maintain an acceptable pace together.
NUMA adds another layer. On a multi-socket server, CPUs, memory and PCIe devices have locality relationships. A process using CPU cores and memory associated with a different locality domain from its GPU can traverse interconnects that local access avoids. The penalty depends on hardware and workload. A compute-heavy kernel may barely notice; a pipeline repeatedly staging data from host memory may expose the difference.
Grouped admission addresses a different failure mode. Starting three workers of a four-worker collective can reserve resources without producing useful progress. Those workers may wait for a missing peer while consuming GPU allocations, CPU reservations and other capacity. A competing job can then hold the resources needed to complete the first group.
The operator’s objective is therefore not simply more occupied GPUs. It is more useful work completed within acceptable queue time, cost and isolation boundaries. Placement efficiency, admission behaviour and application progress need separate measurements because any one of them can improve while another deteriorates.
Separate the three scheduling questions
Treat the release’s listed capabilities as three testable areas rather than one feature bundle. NUMA alignment concerns locality within a host. PodGroup support concerns relationships between workload members. Scheduling-policy combinations concern how choices are ranked or constrained. Each can alter cluster behaviour independently.
| Placement question | Operator test | Evidence to retain |
|---|---|---|
| Are CPUs local to GPUs? | Compare local and remote CPU placement | CPU affinity, topology, step-time distribution |
| Can the group make progress? | Submit a job larger than immediately feasible capacity | Admission events, readiness times, waiting allocations |
| How do policies interact? | Repeat a fragmented-capacity scenario under documented combinations | Placement decisions, queue age, completed work |
| What happens after partial failure? | Prevent one admitted worker from becoming ready | Cleanup time, retry count, stranded GPU-seconds |
Do not assume that a placement preference is a hard constraint. A scheduler might prefer locality but allow a less-local placement when capacity is scarce. Conversely, strict locality may protect execution speed while extending queue time. Both behaviours can be reasonable, but they require different service expectations.
Likewise, group admission is not application readiness. Image pulls, volume attachment, runtime setup and network failures can still delay individual workers after scheduling. Test the full path from submission to useful computation, not merely the transition from Pending to assigned.
Build a topology baseline first
Before changing scheduling policies, inventory representative nodes. Record CPU sockets, NUMA domains, GPU identifiers, PCIe relationships, network interfaces and allocatable resources. Include differences between otherwise similar servers: a different device layout or reserved CPU set can change which placement is actually local.
A small collection pass can establish the baseline:
# Cluster view: allocations, labels and scheduling events
kubectl get nodes -o wide
kubectl describe node <gpu-node>
kubectl get events -n <workload-namespace> --sort-by=.metadata.creationTimestamp

# On an authorised NVIDIA GPU host, where these tools are installed
nvidia-smi topo -m
numactl --hardware
These commands do not configure HAMi or prove that a container receives local CPUs and memory. They expose the host topology and cluster state needed to investigate placement. Capture the workload’s actual CPU affinity and effective memory policy separately, using tools approved for the environment.
Then inspect the relevant kubelet CPU and topology management settings, device allocation path, runtime configuration and workload resource requests. NUMA-aware scheduling cannot compensate for every mismatch downstream. A favourable node choice does not by itself pin application threads or guarantee local memory allocation.
Use an isolated test namespace and a versioned workload specification. Keep the container image, dataset, batch size, worker count and CPU requests constant. Otherwise a changed input pipeline or runtime can masquerade as a scheduling improvement.
Test CPU locality against useful work
Choose a workload with measurable host-to-device activity, then compare a verified local placement with a verified remote or unconstrained placement. Where supported, use an authorised test mechanism to control affinity; do not invent a scheduler configuration key from a release-note headline. Document exactly which layer enforces each setting.
Measure end-to-end duration, median and tail step time, GPU utilisation, CPU utilisation and data-loading wait. Include host-memory pressure and network throughput when available. GPU utilisation alone can be misleading: a busy device may perform less useful work if workers are stalled or computation is repeatedly discarded.
Repeat runs and alternate their order. Cache warmth, thermal conditions and neighbouring workloads can bias a single comparison. Run both an isolated baseline and a controlled contention test, because locality benefits under an empty cluster may not predict behaviour during shared production use.
The decision should incorporate queue time. If strict alignment saves thirty seconds of execution but adds ten minutes of waiting, it may be unsuitable for short interactive tasks. For long training runs, the same preference could be worthwhile. Define workload classes rather than imposing one placement policy on everything.
Test grouped admission and partial placement
Start with a four-worker job when only three compatible worker placements are available. Observe whether no workers are admitted, some are admitted but held, or some begin execution. Record which resources are reserved during the wait and whether unrelated jobs can still make progress.
Next, make the fourth placement available. Measure the interval between that capacity change, scheduling decisions, worker readiness and the first useful training step. This distinguishes scheduler responsiveness from container startup and application rendezvous time. A single overall startup metric conceals where delays originate.
Then force a partial launch failure. For example, use a controlled test in which one worker cannot become ready, without affecting production nodes. Check timeout behaviour, resource release, retry scope and backoff. Determine whether surviving workers remain allocated, are terminated, or are reused according to the workload controller’s documented behaviour.
Also test fairness. A large waiting group should not silently starve smaller jobs indefinitely, and small jobs should not continually prevent a large group from assembling. Scheduling-policy combinations may change this balance. Evaluate queue age by workload class, not just the average across all submissions.
Retain scheduler events and controller logs with timestamps. The useful finding is not merely that a job failed, but whether the failure came from infeasible topology, admission policy, runtime setup or application coordination. Those causes require different remedies.
An illustrative capacity and cost example
Consider an illustrative cluster with four servers, each holding four GPUs: sixteen GPUs in total. Each server has two NUMA domains, with two GPUs associated with each domain. Assume a distributed job requires four workers, each using two GPUs and sixteen CPU cores local to its assigned pair. The job therefore needs eight GPUs and sixty-four local CPU cores.
Suppose every server has two idle GPUs, but only eight eligible local CPU cores remain beside each idle pair. The dashboard reports eight free GPUs and the cluster might have spare cores elsewhere. Nevertheless, none of the four workers satisfies the stated local-CPU constraint. Aggregate GPU availability has not produced even one valid worker placement.
The operator could wait, reduce the request after validating performance, allow remote CPU access, or change competing workload placement. These are service and efficiency choices, not interchangeable fixes. Relaxing locality creates a runnable job only if the remaining constraints are also satisfied.
Now consider a separate partial-placement test on the same cluster. Three two-GPU workers are launched and wait twelve minutes for the fourth. Their blocked allocation is six GPUs multiplied by twelve minutes: seventy-two GPU-minutes, or 1.2 GPU-hours. At an illustrative internal allocation rate of $3 per GPU-hour, that represents $3.60 of assigned capacity without useful progress.
Across twenty such incidents per day, the total becomes twenty-four GPU-hours and $72 in internal allocation cost. Grouped admission that avoids those reservations could reduce stranded allocation. It does not automatically save $72 in cash: owned hardware still incurs costs, and the released capacity must serve useful work or enable a genuine operating-cost reduction.
Finally, suppose verified local placement cuts useful execution from forty to thirty-six minutes on eight GPUs. That saves thirty-two GPU-minutes per completed job, a 10% reduction in execution allocation. But if queue time rises from two to eight minutes, submission-to-completion time rises from forty-two to forty-four minutes. Efficiency improves while turnaround worsens. These hypothetical figures are not HAMi or Clastiq benchmarks.
Sharing mechanisms do not replace placement policy
GPU time slicing, MIG and MPS answer different sharing questions. Time slicing allows workloads to share execution time, but should not be assumed to provide hardware memory partitioning or a guaranteed performance share. MIG, on supported NVIDIA hardware and configurations, creates hardware-partitioned instances. MPS coordinates concurrent CUDA processes, with controls and limitations that depend on the implementation and deployment.
None of these labels alone answers whether Kubernetes GPU sharing has hard limits. Operators must identify the specific resource being limited: device memory, compute allocation, process access or wall-clock consumption. They must also verify the enforcement boundary, failure behaviour and accounting unit. A scheduler request is not necessarily a runtime enforcement mechanism.
For a distributed job, sharing can multiply placement choices while adding variability between workers. One slow worker can determine collective progress. Test interference alongside locality and admission rather than assuming that more schedulable GPU shares mean more predictable throughput.
Use the detailed guidance available through Clastiq for deeper sharing comparisons, and its cluster-operations guide for the broader infrastructure perspective. Keep this release evaluation focused on placement and measured job outcomes.
Connect placement to infrastructure governance
Cognition-AI, based in Muscat, Oman, owns the rFactorial product group. Within that family, Clastiq Orchestrator provides private-cloud orchestration across compute, GPU, storage and networks. Clastiq Lite brings self-service AI and GPU sharing to teams. These supplied capabilities make Clastiq relevant to the operational scope of this story, without implying that it implements HAMi’s NUMA alignment, PodGroup support or scheduling-policy combinations.
The practical workflow starts with a workload contract: required accelerators, CPU and memory needs, dataset access, network expectations, ownership and permitted sharing level. Operators then assess whether the infrastructure can satisfy those requirements together. GPU placement is one stage in that workflow, not a substitute for storage readiness or network capacity.
Governance should distinguish scheduling isolation from security isolation. Local placement does not establish a tenant boundary. Group admission does not authorise dataset access. A shared GPU allocation does not, by itself, demonstrate acceptable separation between organisations or sensitive workloads. Document enforcement at the node, runtime, device, storage and network layers actually deployed.
For teams paying for idle on-premises GPUs, separate unavoidable reserve capacity from fragmentation, blocked allocations and genuine lack of demand. Report useful completed work, queue percentiles, stranded GPU-seconds and idle time by cause. This produces a defensible capacity plan instead of treating every low-utilisation interval as evidence that more aggressive sharing is appropriate.
What to do this week
- Review the HAMi v2.11.0 release notes and document the configuration and prerequisites for each scheduling capability you intend to test.
- Inventory CPU/GPU topology on representative nodes, then verify effective CPU affinity and memory placement inside a controlled workload.
- Run a four-worker admission test with only three feasible placements; retain events, readiness timestamps and reserved-resource measurements.
- Inject one controlled worker startup failure and measure cleanup, retry behaviour and stranded GPU-seconds.
- Compare policy options using both completed-work efficiency and submission-to-completion time, with explicit isolation and fairness requirements.
Explore Clastiq Orchestrator for private-cloud orchestration across compute, GPU, storage and networks, and the rFactorial product family for the wider portfolio owned by Cognition-AI. Keep product evaluation grounded in documented capabilities and workload-specific acceptance tests.